i
DATAIST
Back to feed

Vision and video

Models that see: images, video, generation and visual understanding.

20 articles

Gemini 4 Hydrogen speeds up complex Google searches

Google has updated Search with the Gemini 4 Hydrogen model, which is designed to handle complex queries, typos and multi-part questions more effectively, while showing more links and visual answers. The company says Hydrogen completes tasks 2.5 times faster than its previous fast model, Gemini 3.8 Flash. The update is rolling out to Search users worldwide. The model will also be available in Google AI Studio, the Gemini API, the Gemini app and the paid AI Pro and Ultra plans in the Antigravity development platform.
How can you distinguish video generation from world simulation?

A video can look completely real and still have no idea what happens when you change something in its world. The authors draw a clear line between models that create convincing images and models that track how an environment changes over time, remember what has happened, and respond consistently to actions. They also introduce WorldFoundry, an open platform for running and comparing these systems across video, 3D scenes, and interactive environments, with evidence attached to each evaluation. In this review we look at what it takes for an AI system to move beyond generating plausible visuals and become a model of a world that can be tested, changed, and explored.

“I feel half-dressed at Grand Central without a storyboard”: cinema pushes back against AI

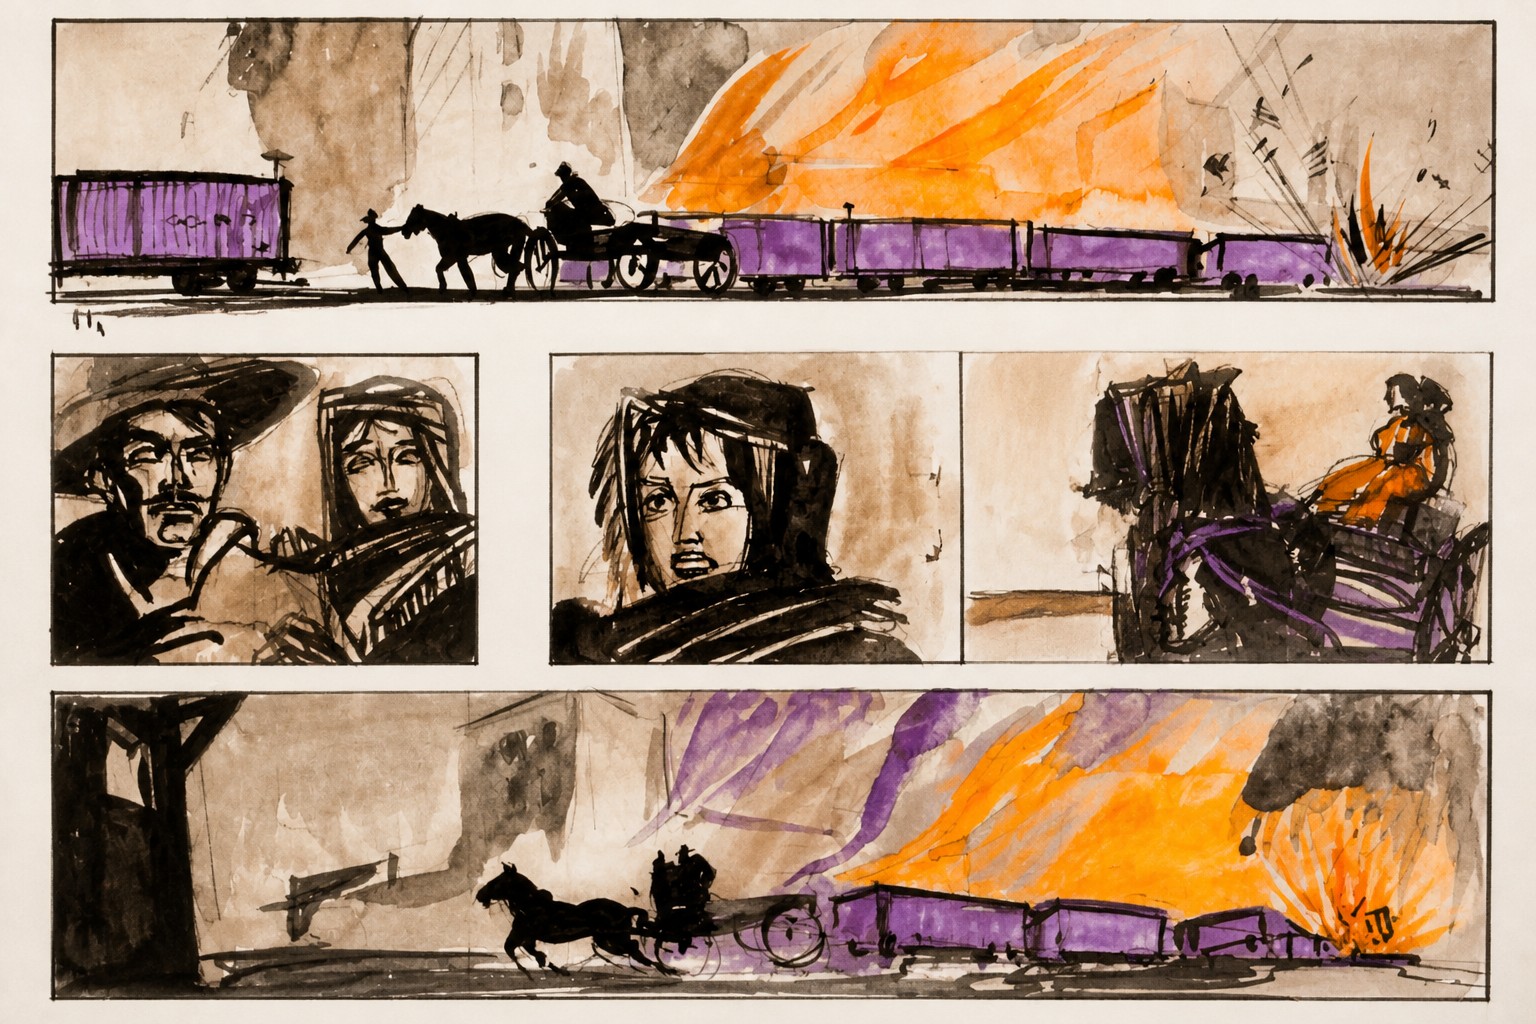
Hollywood is adopting generative AI, putting storyboard artists at risk. These specialists draw a sequence of images to map out a film’s scenes in advance. The panels help directors shape a film’s visual language and explain their ideas to actors and crew. Now, images can be generated from text prompts. Even Martin Scorsese has used a text model to generate images while preparing the storyboard for his next film.

Google launches Language Explorer to explore linguistic diversity

Google has introduced Language Explorer, an interactive web platform that helps researchers, teachers and anyone interested in languages explore how they are distributed through data and visualizations. The project is also part of the Real Talk! Sprache. Macht. Welt. exhibition at the Museum of Communication in Berlin. The platform brings together information on thousands of languages and was created as part of the 1,000 Languages Initiative, using the open LinguaMeta dataset.

Flint-interactive moves chart behavior into the compiler

AI-generated charts can answer a question, but they often stop at the view their author chose. Flint-interactive is a language for building visualizations that readers can explore: select data, change a view and connect a chart to other parts of an application. Built on Flint, it lets developers and AI agents describe interactions at a higher level instead of managing low-level display behavior themselves. The pitch is practical: make interactive charts easier to generate and more dependable, without asking an agent to repeatedly write and debug custom code.

Elorian’s Glimpse model revisits images as it reasons

Elorian has released Glimpse, a model designed to inspect images again while it reasons, rather than rely on a single conversion of the image into tokens. It can crop an area, extract frames from video or run code to measure and compare what it sees. The company calls this a “visual scratchpad” and says a small team trained the model using several hundred GPUs. Its pitch is not that image inspection is new, but that it can be the organizing idea of a smaller, cheaper model.

How Virtual Worlds Help Agents Learn Faster

An AI agent can only learn from the worlds it gets to explore, so what happens when those worlds are both realistic and easy to expand? The authors introduce AgentGarten, a system that combines interactive simulators with a shared visual engine, giving agents worlds with consistent rules and lifelike scenes. Agents learn by acting, then pass useful experience to later agents through reusable playbooks, helping them improve with far fewer rounds of practice than conventional training. In this review we look at how AgentGarten builds its virtual worlds, turns each agent’s experience into a foundation for the next, and could make ongoing learning more practical.

Magnific One wraps GPT Image 2 in a brand-control workflow

Magnific has launched Magnific One, an image-generation product built around a practical promise: make images feel less like AI output while keeping them within a company’s visual style. The product uses OpenAI’s GPT Image 2 with Magnific’s creative-guidance system, which interprets prompts, applies references and brand rules, and checks generated images for problems. The announcement’s strongest case is not that Magnific has a better underlying model, but that it can make image generation more predictable for professional teams.

ChatGPT turns some answers into interactive graphics

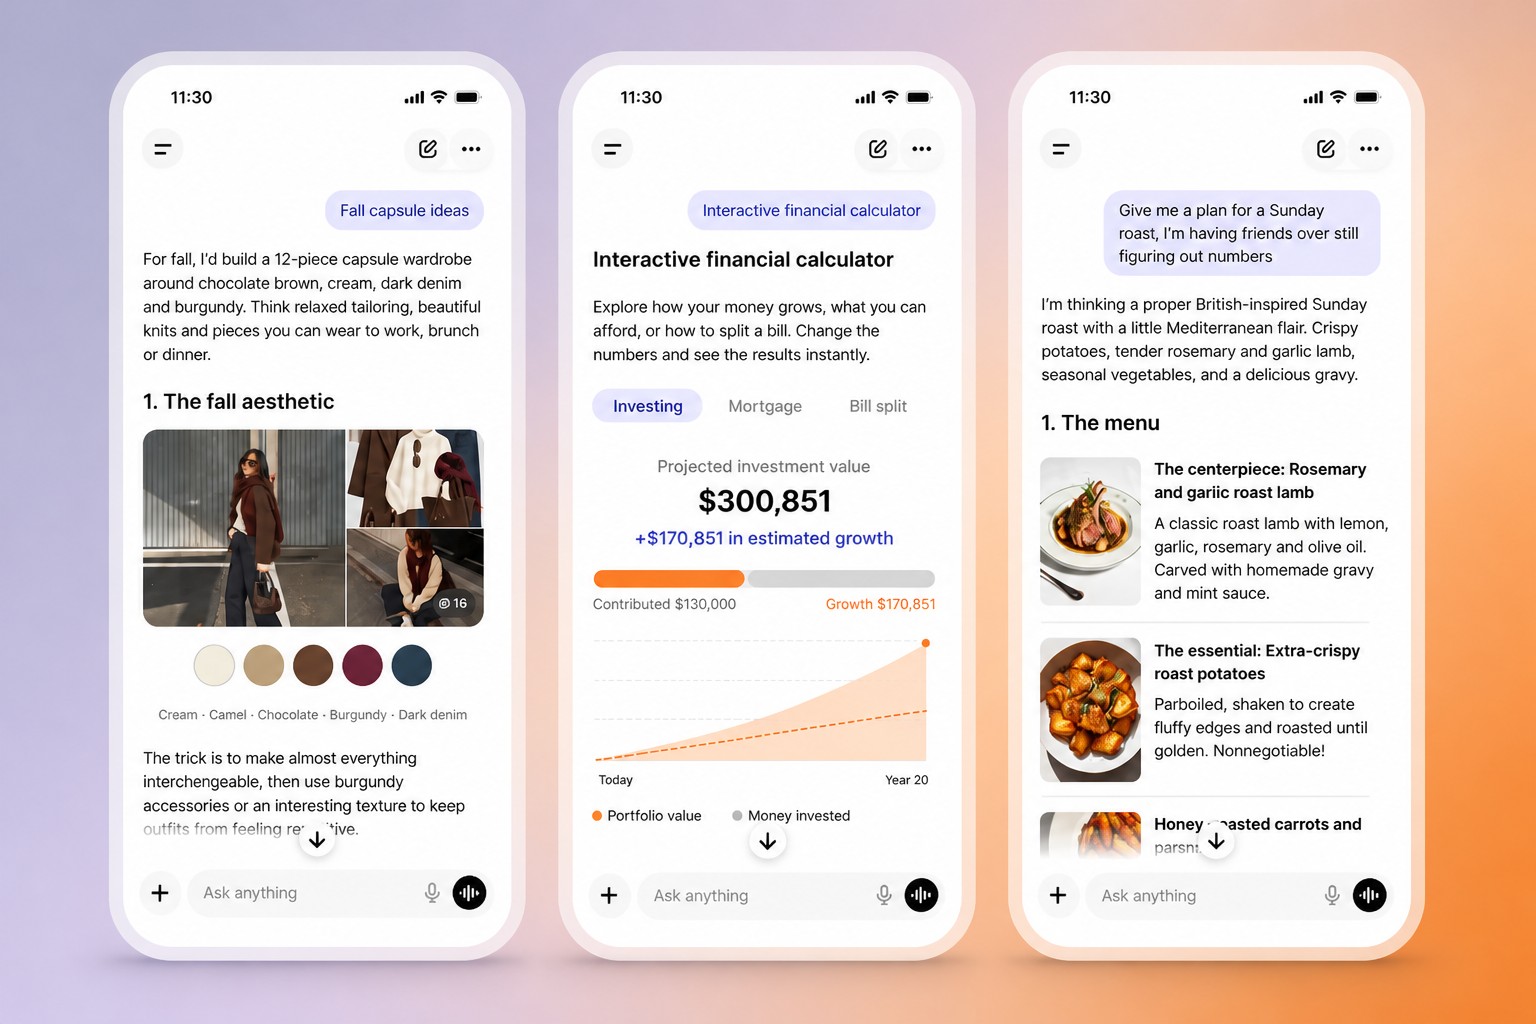
ChatGPT is adding interactive graphics to some answers, turning questions about subjects such as aircraft seating and apartment costs into visual tools users can manipulate. The change matters because it makes the interface itself more responsive: instead of returning the same block of text to everyone, ChatGPT can show a custom diagram or calculator. But OpenAI says these elements will not appear in every answer, and users can ask to see them less often.

How to create a video from a spreadsheet without spending hours editing it

A spreadsheet can hold a story, but turning it into a polished video usually takes far more than pressing play. The authors introduce DataMagic, a system that turns raw tables into videos with charts, narration, and animations that stay in sync. It first drafts possible scenes, then arranges them into a coherent story, while keeping every visual tied to its source data so the facts can be checked. People can also step in to guide or refine the process instead of handing everything over to AI. In this review we look at how DataMagic brings data, storytelling, and video editing together, and how it helps people create data videos faster without losing control or accuracy.

Shopify’s Canvas brings AI chat into store design

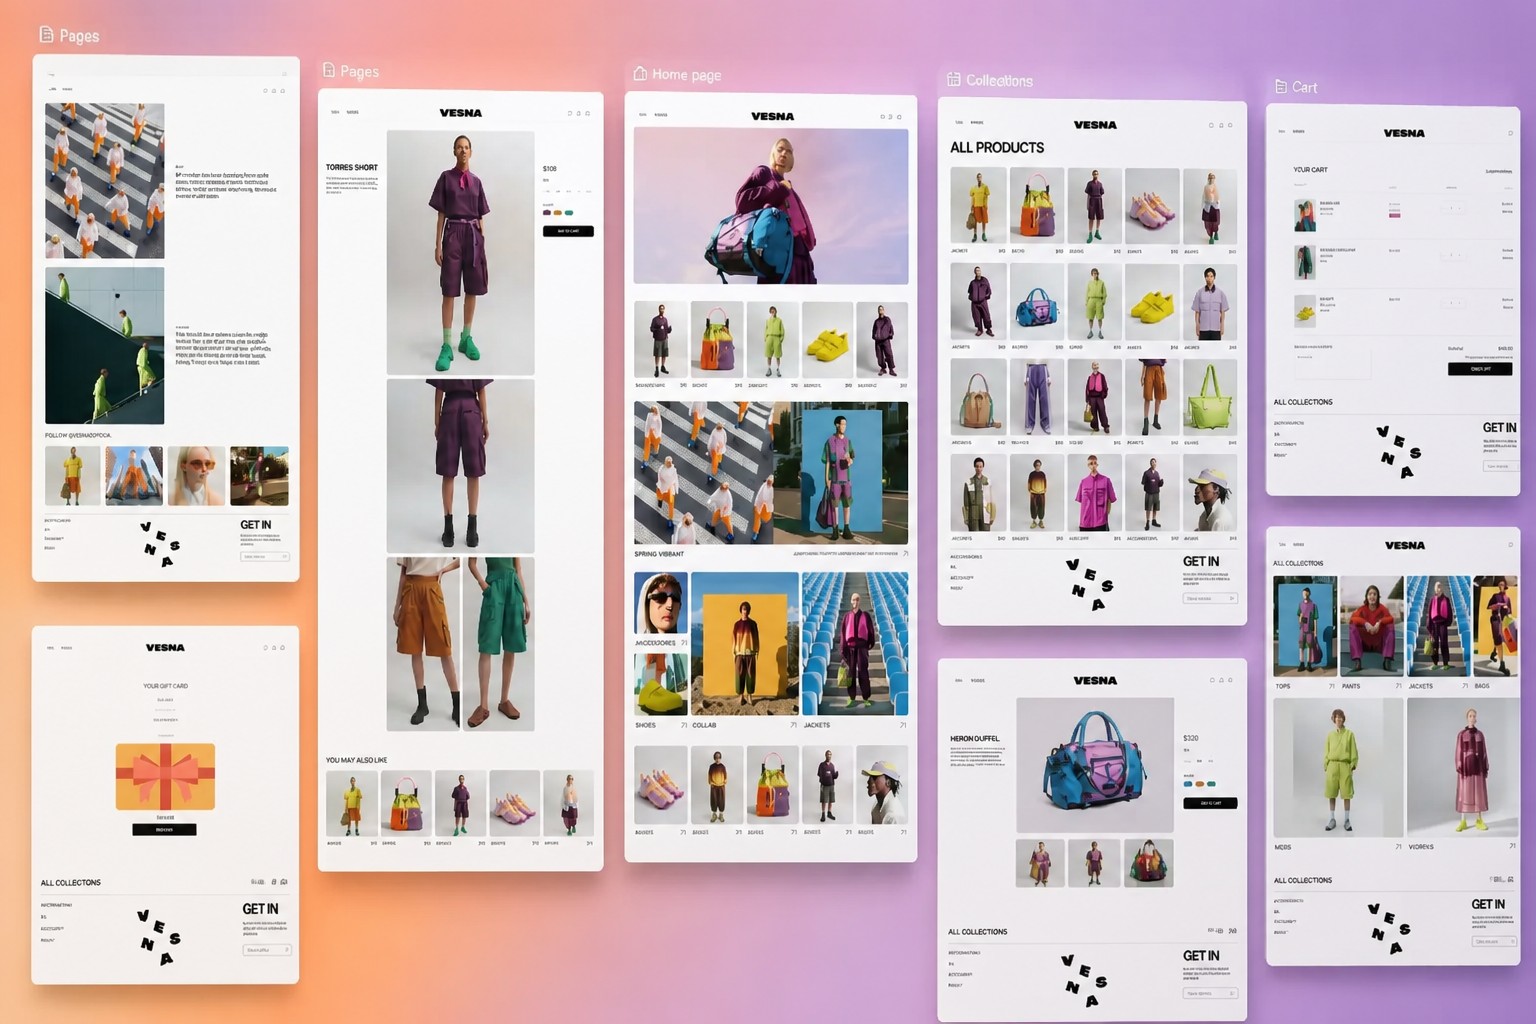
Shopify has introduced Canvas, a visual workspace where merchants can ask its Sidekick AI assistant to change an online store through chat. The tool shows edits against the store’s real code as they happen, rather than offering only a static mockup. That could make store design more accessible to merchants without developers, but Canvas is an early release: it works only on desktop and does not yet support third-party themes or several other Shopify features.

Worldmodeldata is betting game footage can train AI world models

A British startup wants to turn video-game play into training data for AI world models, systems designed to learn how actions change the physical world. Worldmodeldata says it has licensed nearly one million hours of gameplay from studios behind popular games. The pitch is that games already produce vast streams of visual scenes paired with player inputs, offering researchers data that is difficult to collect by hand. But the approach has a central limitation: a game can look real without behaving like the world a robot must handle.

Google’s AI video director targets long-form continuity

Google has introduced an AI video director designed to keep multi-scene stories coherent for several minutes. The multi-agent system sits above Gemini and Veo, coordinating prompts, story structure, visual continuity and quality checks instead of treating each clip as an isolated generation. The research addresses a central weakness of current video pipelines: small inconsistencies in one shot can spread through the rest of a production, leaving humans to repair the result.

Black Forest Labs takes FLUX 3 Action into robotics

Black Forest Labs has released FLUX 3 Action, a robotics model designed to turn visual predictions into robot actions, and says it will publish the weights, source code and fine-tuning recipe. On NVIDIA’s RoboLab-120 simulation benchmark, the 7-billion-parameter model scored 42.92%, beating the 16-billion-parameter Cosmos3-Nano-Policy by 6.1 percentage points. The result matters less as a definitive robotics leaderboard victory than as a test of BFL’s larger bet: that a model pretrained on images, video and audio can be adapted to physical work without starting from a giant robotics-specific system.

Perceptron's Isaac 0.5 is open, its video sources are not

Perceptron, a company founded in November 2024 by two former Meta scientists, released Isaac 0.5 this week — a vision model its creators say gives machines the ability to "perceive, reason and act" in industrial settings. The software is aimed at robots with computer vision moving through warehouses and shop floors, and at companies that want to extract visual data from the video those robots…

Blue Jays keep insisting a human drew their Nestea cartoon

The Toronto Blue Jays' account posted a short cartoon made as an advertising partnership with Nestea, the Nestlé drink, in the visual register of adult animated series like BoJack Horseman and Family Guy. It carries the familiar tells of hurried generative AI: hands drawn wrong and tangled together, lettering that resolves into nothing. A community note attached to the post listed them —…

Predicting the answer's latent image beats text-only chain of thought

Multimodal LLMs have learned to recognize objects, but how do you give them visual imagination? A look at the Cognitive Supersensing idea. Over the past few years, multimodal LLMs (MLLMs) have learned to recognize objects, read captions, answer questions about an image and even give a decent account of what is happening in a frame. But they have…

GroundCUA matches desktop grounding baselines with 700K examples, not 9M

Agents that operate a computer keep failing at a step that looks trivial: finding the element on screen that a human instruction describes. That grounding is hardest on interfaces crowded with tiny controls, near-identical panels, high resolution, visual noise and rendering artifacts. The GroundCUA team shows how to solve this narrow but load-bearing problem — making the link between language…

Sora-2 solves visual puzzles by drawing its reasoning in video

When we ask a model to reason, it reasons in words if the medium is text, or over a static scene if the medium is an image. The world, though, is not static: objects move, and the rules often only become visible in how those objects behave over time. The authors propose video generation as a general-purpose channel for reasoning. Text can be written directly into the frames, visual hypotheses…

LLMs score 70+ on game code but under 25 on how the game looks

Making a game is more than getting code to run. It takes mechanics a player can grasp, art that looks decent, smooth animation and a steady 60 FPS. Large language models handle algorithmic problems confidently, but evaluations of their code rarely account for playability or aesthetics. The authors of V-GameGym set out to fill that gap: they assembled a realistic benchmark for visual game…